2026
CUDACoach: Guiding CUDA Kernel Optimization with Diverse Strategies Learned from Verified Code
Submitted to ICLR 2027 Under Review
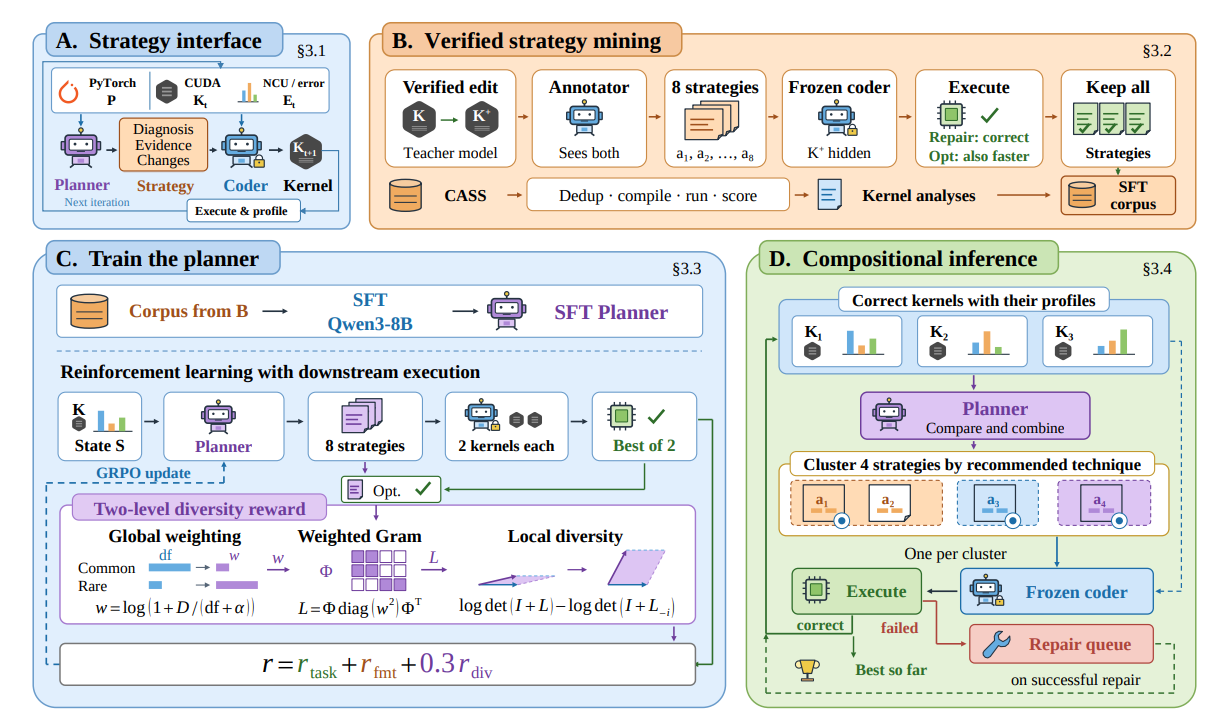
CUDACoach learns repair and optimization strategies to guide a frozen coder through verified strategy mining and reinforcement learning with a two-level diversity reward. Evaluated on all 250 KernelBench tasks with three downstream coders, it achieves 60.4% correctness with Qwen3-Coder-Plus and produces correct kernels faster than PyTorch on 19.2% of tasks.
CUDACoach: Guiding CUDA Kernel Optimization with Diverse Strategies Learned from Verified Code
Submitted to ICLR 2027 Under Review
CUDACoach learns repair and optimization strategies to guide a frozen coder through verified strategy mining and reinforcement learning with a two-level diversity reward. Evaluated on all 250 KernelBench tasks with three downstream coders, it achieves 60.4% correctness with Qwen3-Coder-Plus and produces correct kernels faster than PyTorch on 19.2% of tasks.
NovGauge: A Fine-Grained Benchmark for Diagnosing LLMs' Capability in Paper Novelty Assessment
Submitted to EMNLP 2026 Under Review
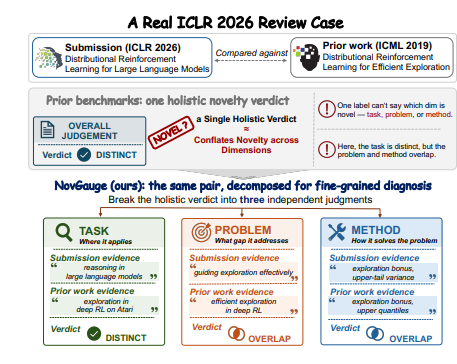
NovGauge is a human-anchored benchmark for diagnosing LLM-based scientific novelty assessment across task, problem, and method dimensions. Evaluation of 18 LLMs on 619 paper pairs and 50 multi-paper sets shows that faithfulness verification reduces most models' raw F1 by more than half, exposing substantial hallucination and unsupported-evidence failures.
NovGauge: A Fine-Grained Benchmark for Diagnosing LLMs' Capability in Paper Novelty Assessment
Submitted to EMNLP 2026 Under Review
NovGauge is a human-anchored benchmark for diagnosing LLM-based scientific novelty assessment across task, problem, and method dimensions. Evaluation of 18 LLMs on 619 paper pairs and 50 multi-paper sets shows that faithfulness verification reduces most models' raw F1 by more than half, exposing substantial hallucination and unsupported-evidence failures.