
AI Elite Class, 2024 Cohort
I am a third-year undergraduate student in the AI Elite Class at the College of Computer Science and Artificial Intelligence, Fudan University.
My research interests lie in Large Language Models (LLMs), AI Agents, and Interpretability. I am currently working as a research intern at the Fudan NLP Group, led by Professor Qi Zhang and Associate Professor Tao Gui.
“The only thing we have to fear is fear itself—nameless, unreasoning, unjustified terror which paralyzes needed efforts to convert retreat into advance.”
Education
-
 Fudan UniversityCollege of Computer Science and Artificial Intelligence
B.S. in Artificial IntelligenceAug. 2024 - present
Experience
-
 Fudan NLP GroupResearch InternDec. 2025 - present
Honors & Awards
-
复旦大学优秀学生奖学金二等奖2025
Selected Publications (view all )
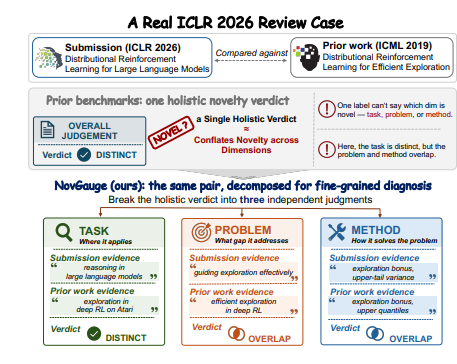
NovGauge: A Fine-Grained Benchmark for Diagnosing LLMs' Capability in Paper Novelty Assessment
Submitted to EMNLP 2026 Under Review
NovGauge is a human-anchored benchmark for diagnosing LLM-based scientific novelty assessment across task, problem, and method dimensions. Evaluation of 18 LLMs on 619 paper pairs and 50 multi-paper sets shows that faithfulness verification reduces most models' raw F1 by more than half, exposing substantial hallucination and unsupported-evidence failures.