2026
NovGauge: A Fine-Grained Benchmark for Diagnosing LLMs' Capability in Paper Novelty Assessment
Submitted to EMNLP 2026 Under Review
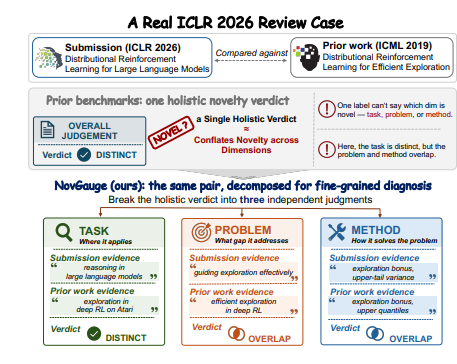
NovGauge is a human-anchored benchmark for diagnosing LLM-based scientific novelty assessment across task, problem, and method dimensions. Evaluation of 18 LLMs on 619 paper pairs and 50 multi-paper sets shows that faithfulness verification reduces most models' raw F1 by more than half, exposing substantial hallucination and unsupported-evidence failures.